Area All 23 Core ML 14 LLMs 6 Embodied AI 8 Computer Vision 2
Research Themes All 23 RL Post-Training 7 Scalable RL 4 Plasticity Loss 4 Exploration 4 Efficiency 10 Generalization 3
Area All · 23 Core ML · 14 LLMs · 6 Embodied AI · 8 Computer Vision · 2 Theme All · 23 RL Post-Training · 7 Scalable RL · 4 Plasticity Loss · 4 Exploration · 4 Efficiency · 10 Generalization · 3
Role All · 23 First & co-first · 10 Co-author · 13 Status All · 23 Published · 15 Accepted · 3 Preprint · 5
23 publications
Clear filters Guozheng Ma, Qi Zhao, Lu Li, Zilin Wang, Pierre-Luc Bacon, Dacheng Tao
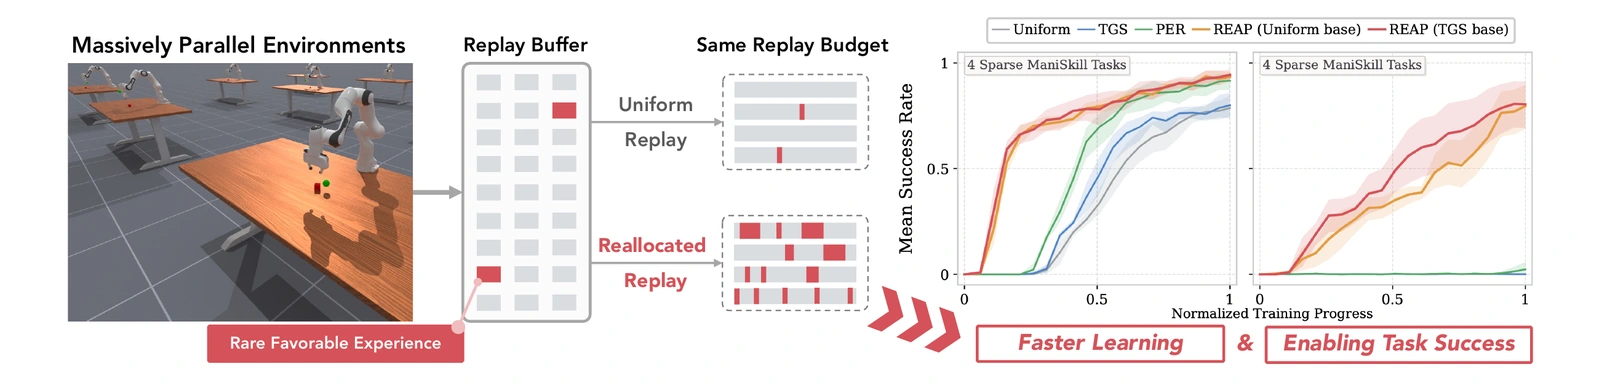
Discovering successful behavior does not guarantee that a policy learns to reproduce it. REAP reallocates an existing replay budget toward high-return experience, improving learning across 48 control tasks without increasing interaction or update budgets.
Guozheng Ma, Lu Li, Zilin Wang, Pierre-Luc Bacon, Dacheng Tao
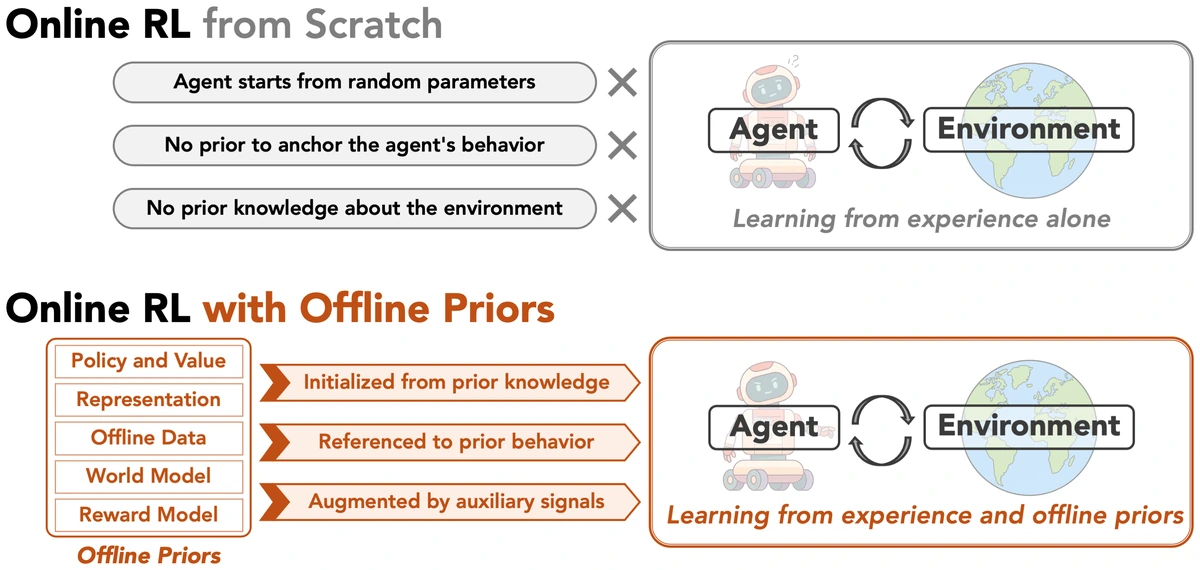
Let deployment evidence guide how online learners use and adapt their offline priors.
Guozheng Ma, Lu Li, Haoyu Wang, Zixuan Liu, Pierre-Luc Bacon, Dacheng Tao
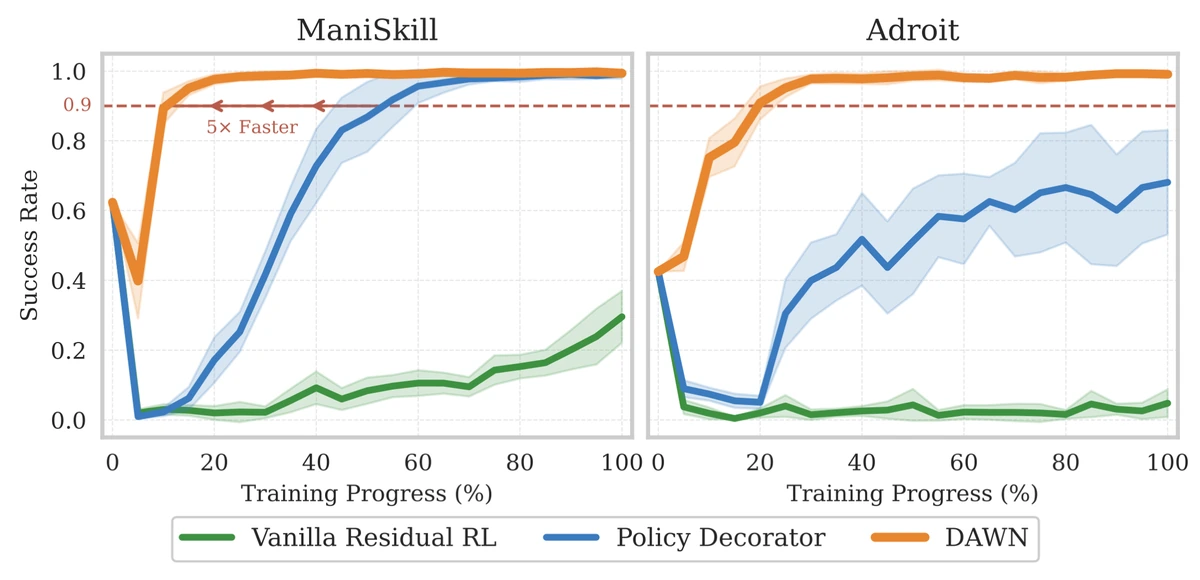
Helping residual RL critics learn from a pretrained policy and recognize small action corrections.
Themes RL Post-Training Efficiency Yilun Kong, Yunpeng Qing, Guozheng Ma, Haoyu Wang, Li Shen, Zhi Hou, Dacheng Tao
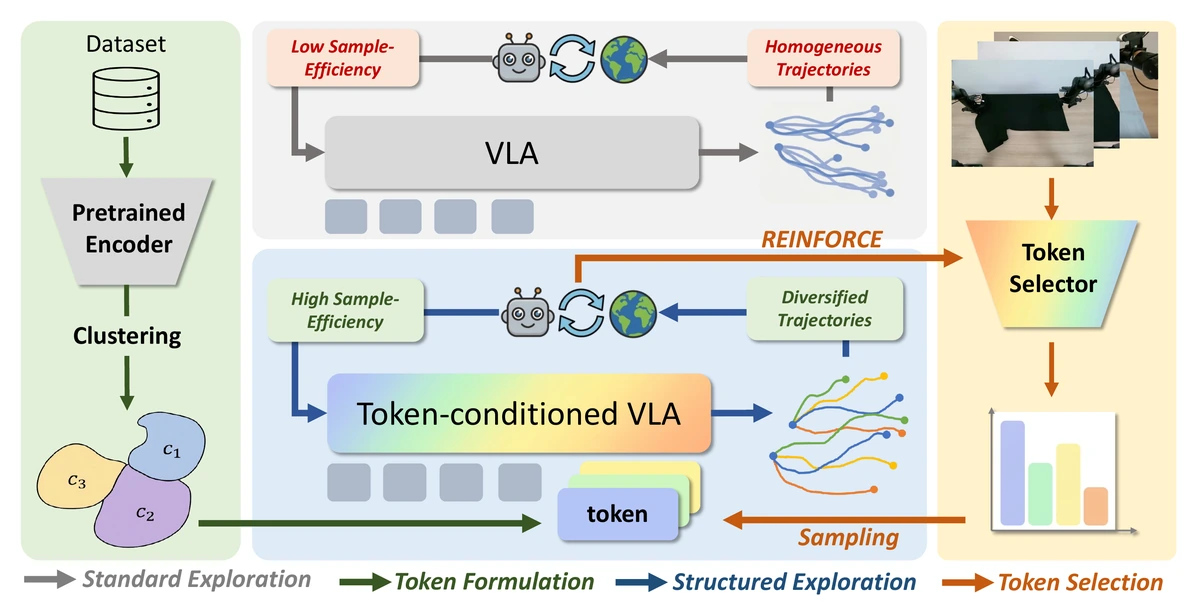
Behavior tokens derived from offline demonstrations guide more diverse exploration during reinforcement finetuning of vision-language-action models.
Themes RL Post-Training Exploration Efficiency Junjie Zhang, Guozheng Ma, Shunyu Liu, Haoyu Wang, Jiaxing Huang, Ting-En Lin, Fei Huang, Yongbin Li, Dacheng Tao
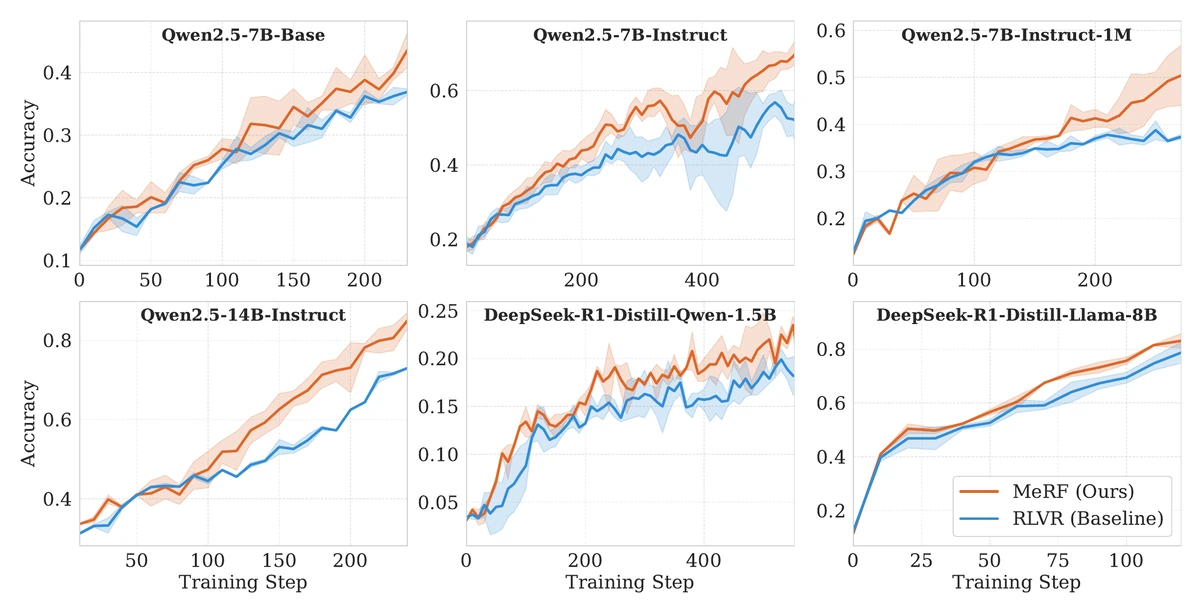
Providing reward rules directly in the prompt helps large reasoning models use reinforcement finetuning more efficiently.
Themes RL Post-Training Efficiency Shengchao Hu*, Peng Wang*, Guozheng Ma, Shi Fu, Li Shen, Ya Zhang, Dacheng Tao * Equal contribution
A systematic comparison examines how reinforcement finetuning and parameter-update choices affect the adaptation of pretrained Transformer-based agents.
Haoyu Wang, Guozheng Ma, Shugang Cui, Yilun Kong, Haotian Luo, Li Shen, Mengya Gao, Yichao Wu, Xiaogang Wang, Dacheng Tao
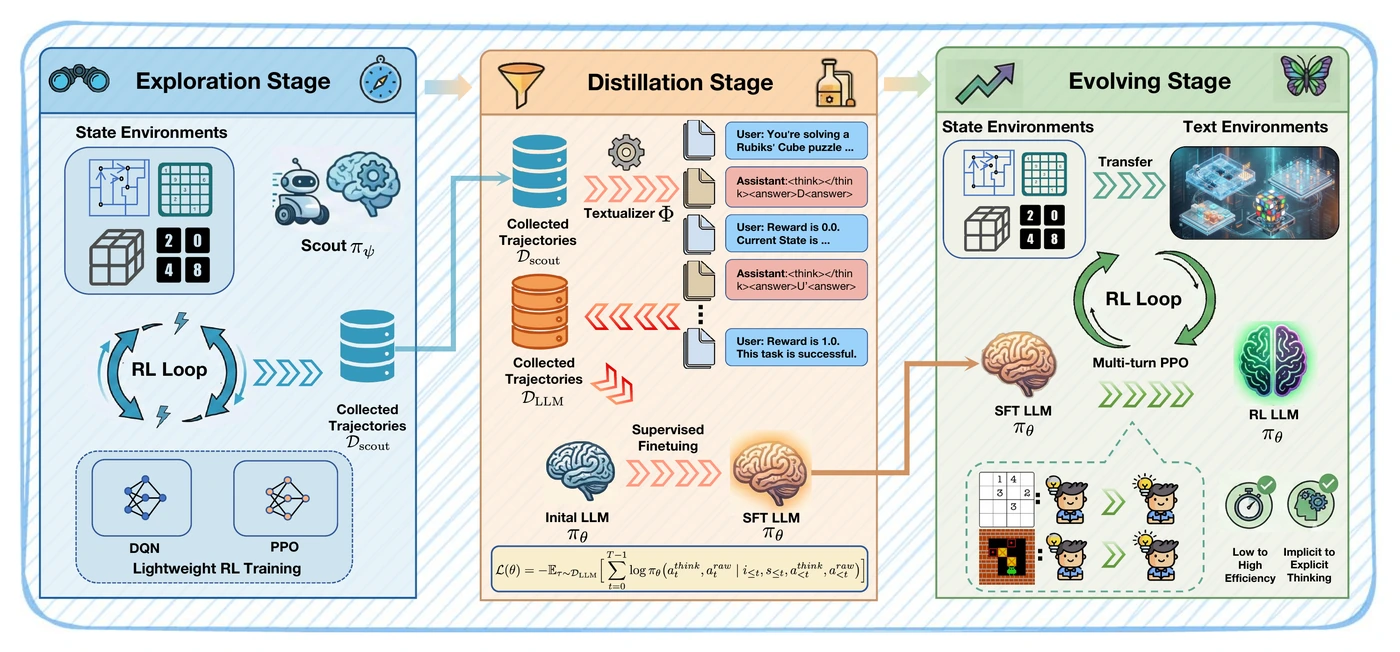
Lightweight scouts collect exploratory experience that helps language agents learn unfamiliar tasks more efficiently than language-only trial and error.
Themes RL Post-Training Exploration Efficiency Haotian Luo*, Huaisong Zhang*, Xuelin Zhang*, Haoyu Wang*, Zeyu Qin*, Wenjie Lu*, Guozheng Ma, Haiying He, Yingsha Xie, Qiyang Zhou, Zixuan Hu, Hongze Mi, Yibo Wang, Naiqiang Tan, Hong Chen, Yi R. Fung, Chun Yuan, Li Shen * Equal contribution
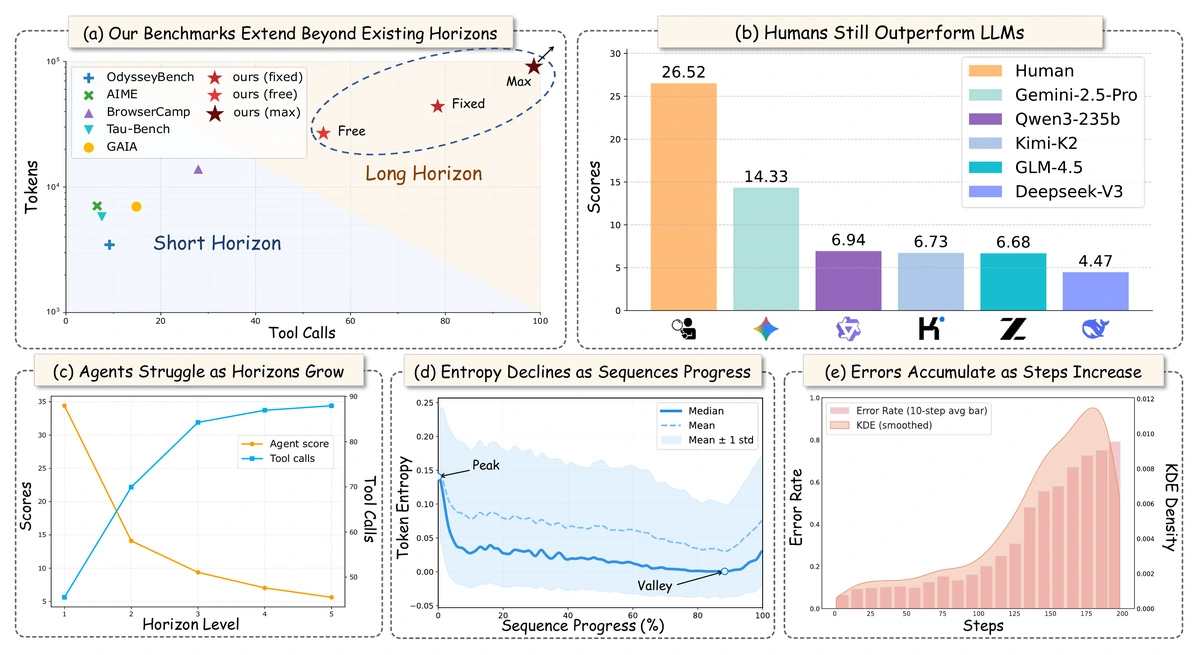
A benchmark for sustained exploration, reasoning, memory and tool use over long trajectories in partially observable environments.
Junjie Zhang, Guozheng Ma, Shunyu Liu, Zetian Hu, Yongcheng Jing, Ting-En Lin, Yongbin Li, Dacheng Tao
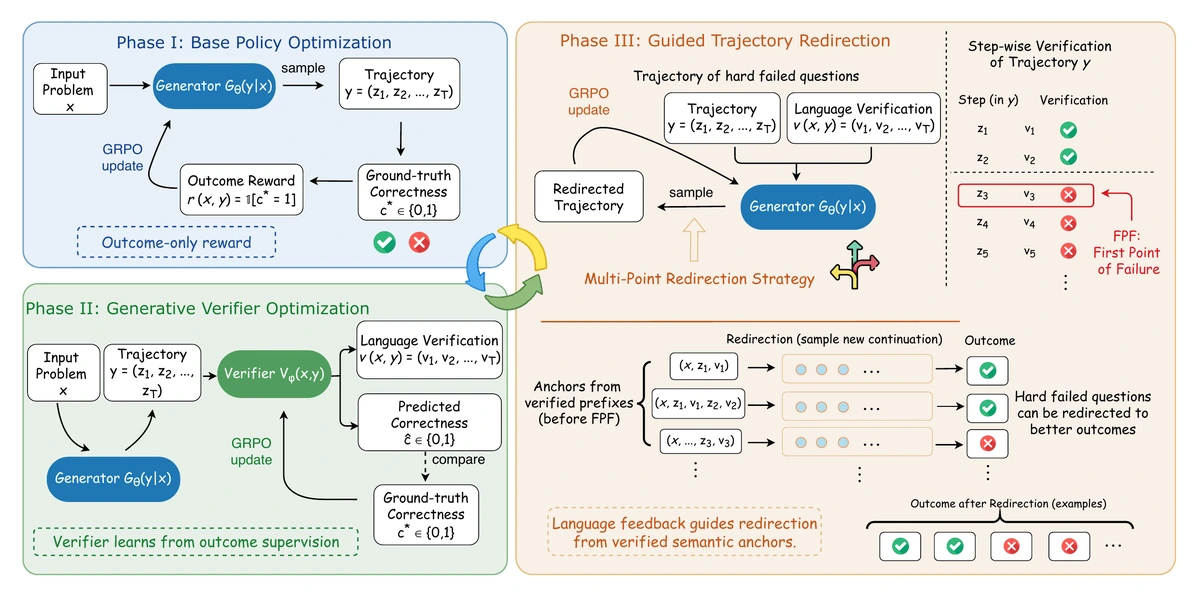
A jointly trained verifier supplies stepwise language critiques that redirect reasoning trajectories and support better LLM learning.
Qi Zhao, Guozheng Ma, Yilun Kong, Lu Li, Haoyu Wang, Zilin Wang, Tiantian Zhang, Yuxing Wang, Jian Sha, Yongzhe Chang, Xueqian Wang, Dacheng Tao
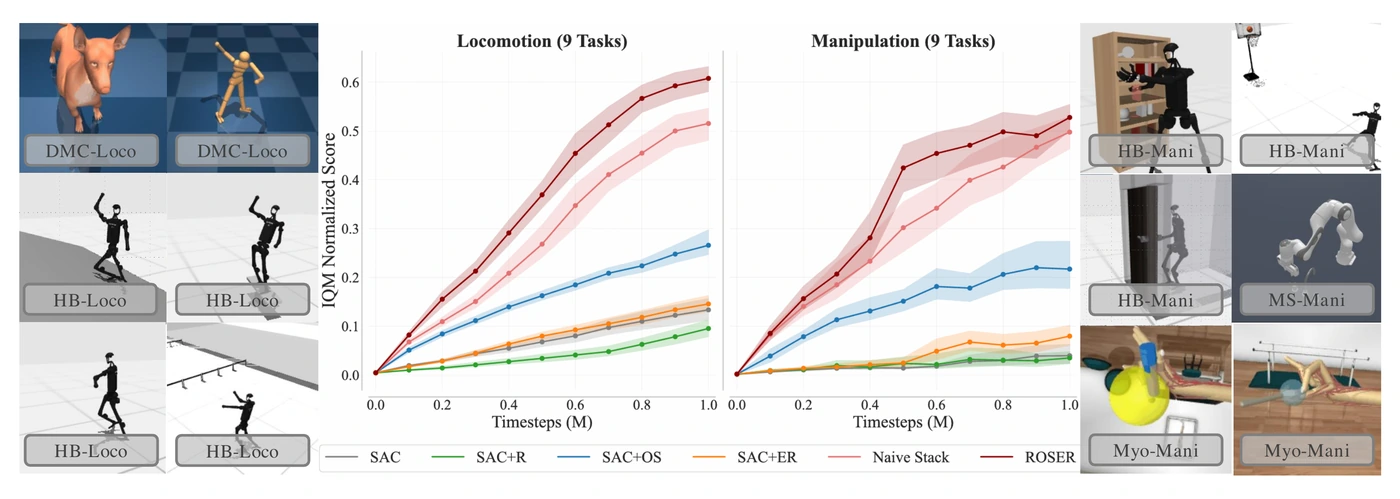
Coordinating representation learning, optimization stability and experience replay improves how continuous-control agents benefit from interacting algorithm components.
Chengbo Wang, Guozheng Ma, Jinhong Wu, Tie Ji, Yizhen Lao
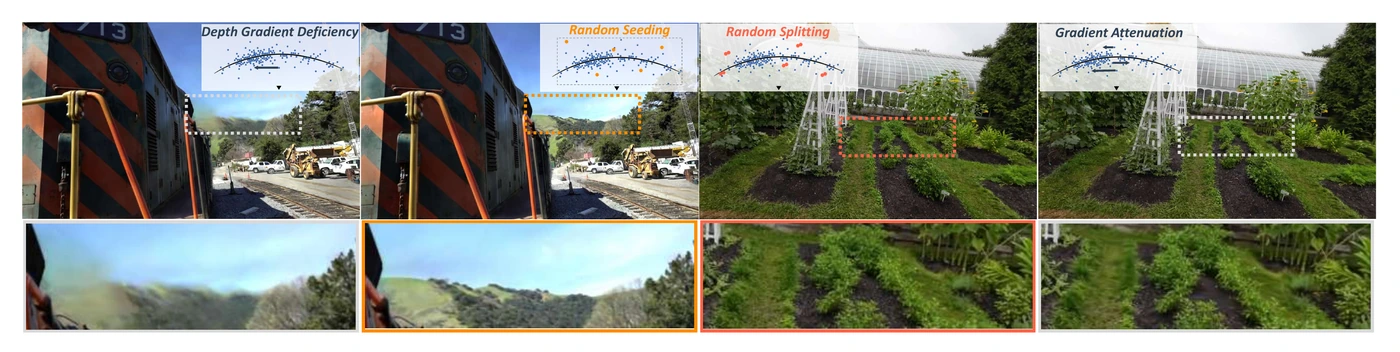
Explicit exploration through random seeding and splitting helps Gaussian Splatting escape optimization biases that leave reconstructions blurry.
Guozheng Ma*, Lu Li*, Zilin Wang, Li Shen, Pierre-Luc Bacon, Dacheng Tao * Equal contribution
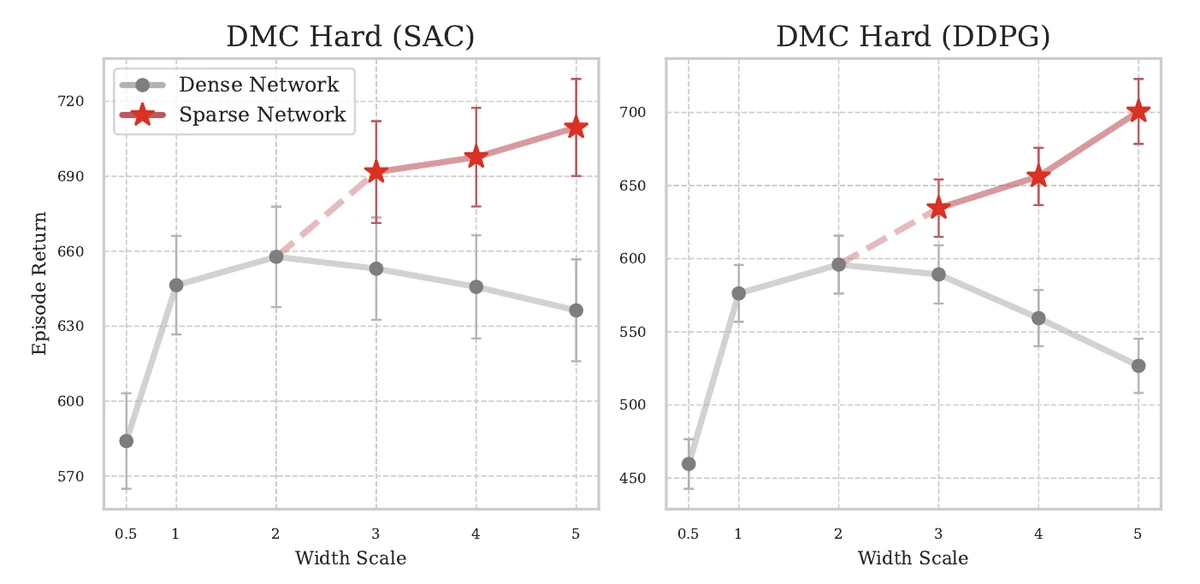
Randomly pruning a network before training improves how deep RL scales.
Themes Scalable RL Plasticity Loss Chengbo Wang, Guozheng Ma, Yifei Xue, Yizhen Lao
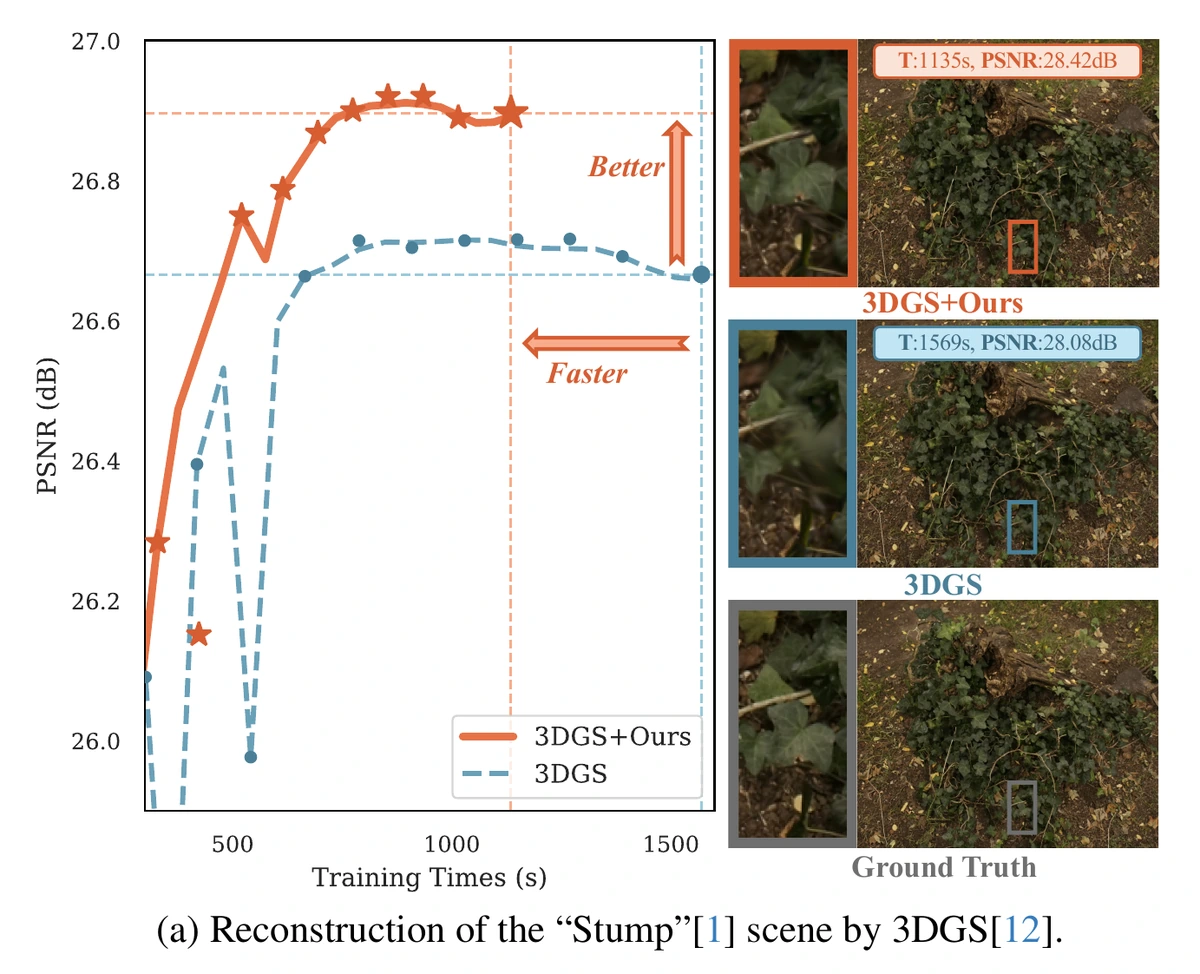
Periodically training selected groups of Gaussian primitives improves the efficiency and rendering quality of 3D scene reconstruction.
Yilun Kong, Guozheng Ma, Qi Zhao, Haoyu Wang, Li Shen, Xueqian Wang, Dacheng Tao
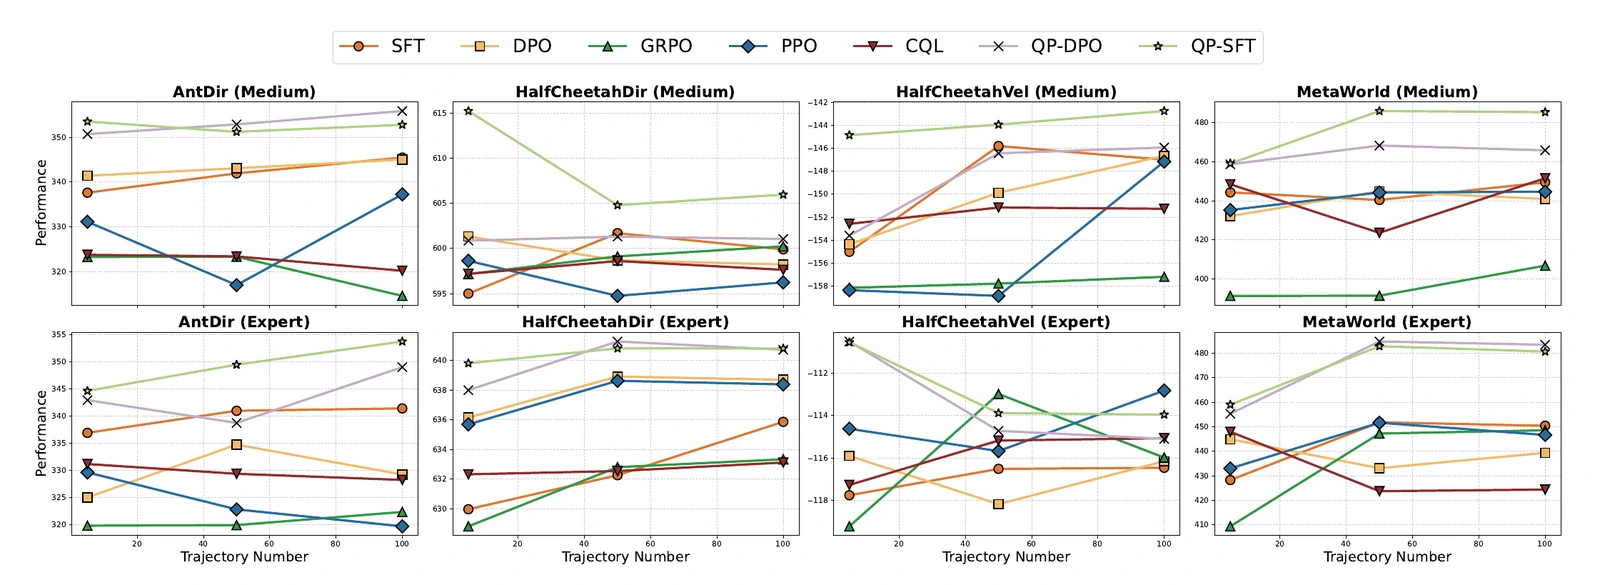
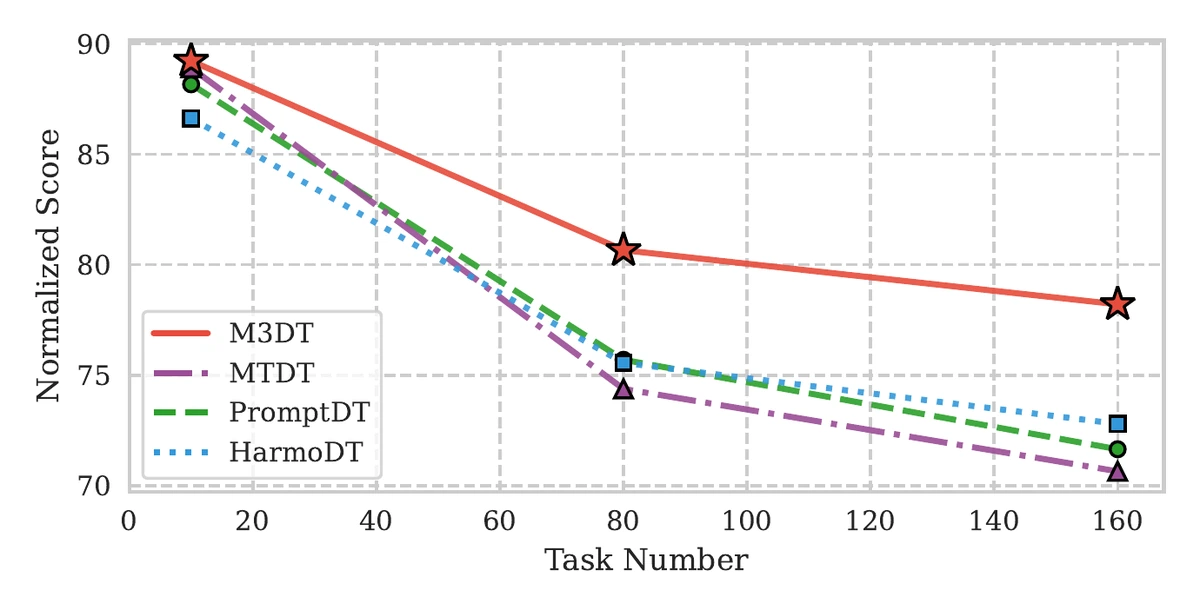
Mixture-of-expert decision transformers combine architectural and training changes to scale offline reinforcement learning across many distinct tasks.
Guozheng Ma, Zhen Wang, Zhecheng Yuan, Xueqian Wang, Bo Yuan, Dacheng Tao
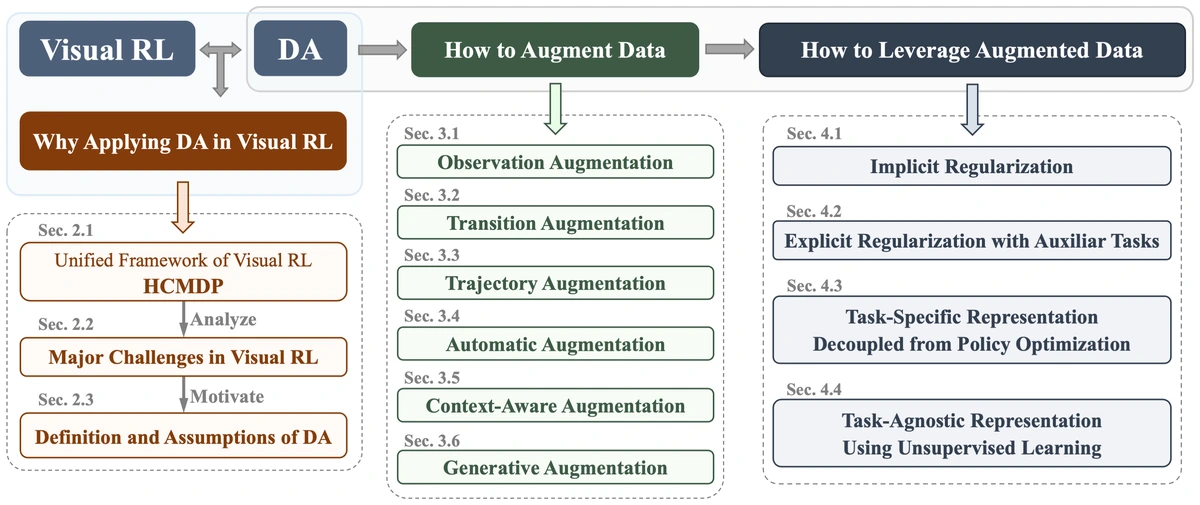
A framework for understanding how augmented data supports visual reinforcement learning.
Guozheng Ma, Lu Li, Zilin Wang, Haoyu Wang, Shengchao Hu, Leszek Rutkowski, Dacheng Tao
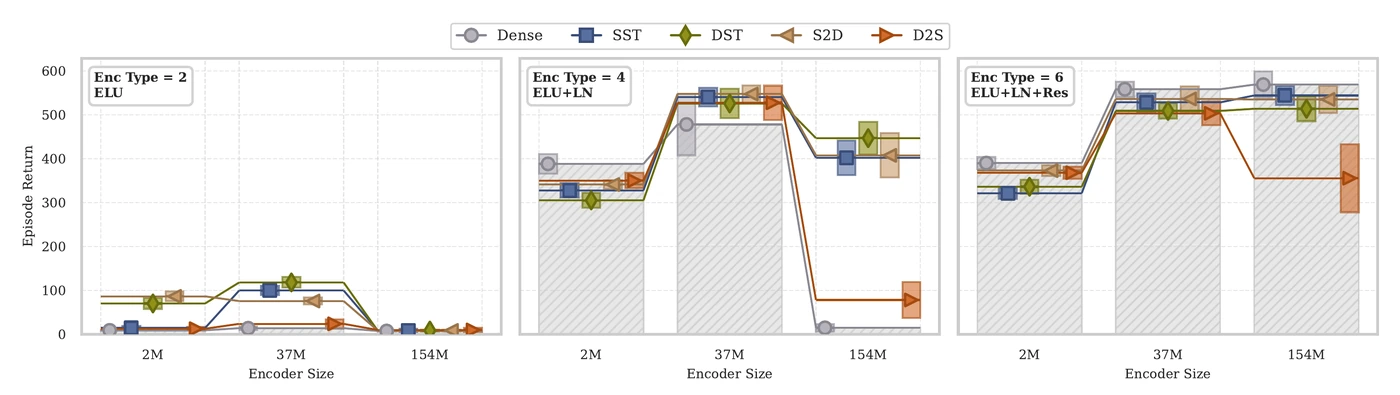
Module-specific sparse training complements architectural improvements by adapting training strategies to the different roles inside deep RL networks.
Themes Scalable RL Plasticity Loss Mingqi Yuan*, Qi Wang*, Guozheng Ma*, Caihao Sun*, Bo Li, Xin Jin, Yunbo Wang, Xiaokang Yang, Wenjun Zeng, Dacheng Tao, Jiayu Chen * Equal contribution
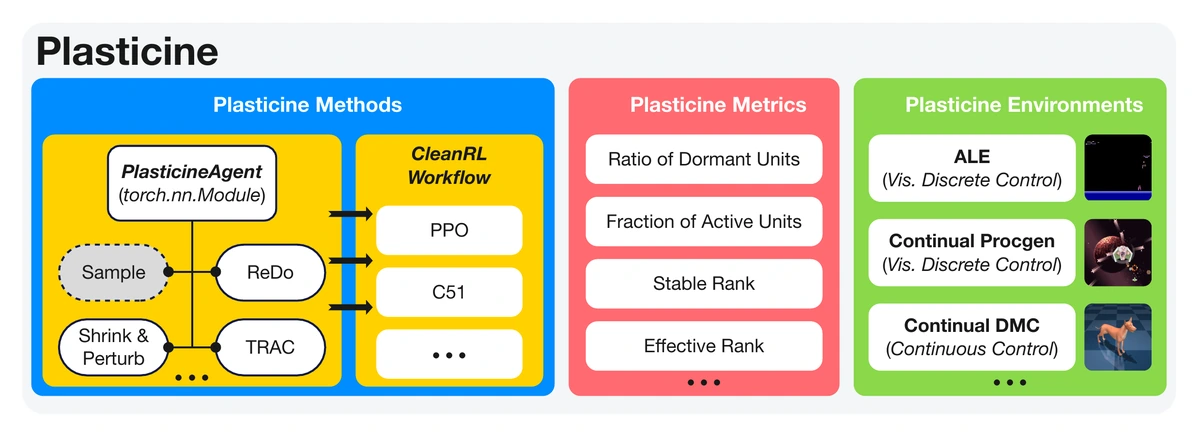
A shared implementation and evaluation framework makes it easier to compare plasticity loss and mitigation methods in deep RL.
Haoyu Wang*, Guozheng Ma*, Cong Yu, Ning Gui, Linrui Zhang, Zhiqi Huang, Suwei Ma, Yongzhe Chang, Sen Zhang, Li Shen, Xueqian Wang, Peilin Zhao, Dacheng Tao * Equal contribution
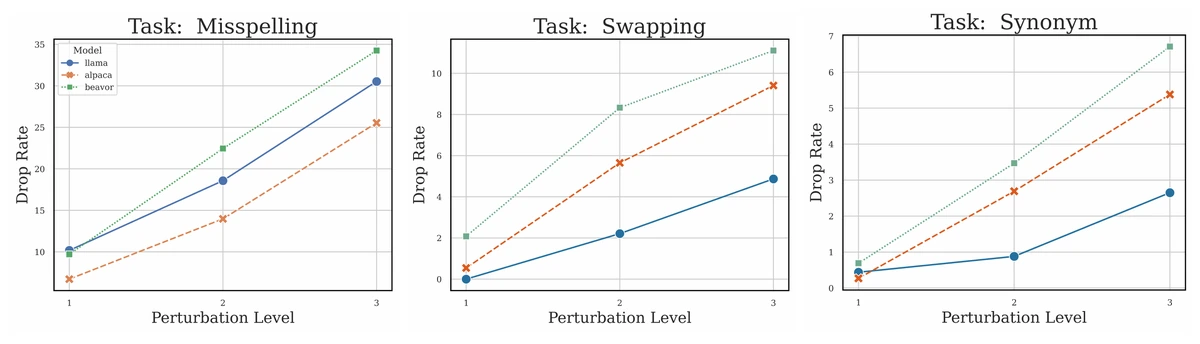
Using reward models to measure how everyday word-level changes affect the quality of generated language-model responses.
Guozheng Ma*, Lu Li*, Sen Zhang, Zixuan Liu, Zhen Wang, Yixin Chen, Li Shen, Xueqian Wang, Dacheng Tao * Equal contribution
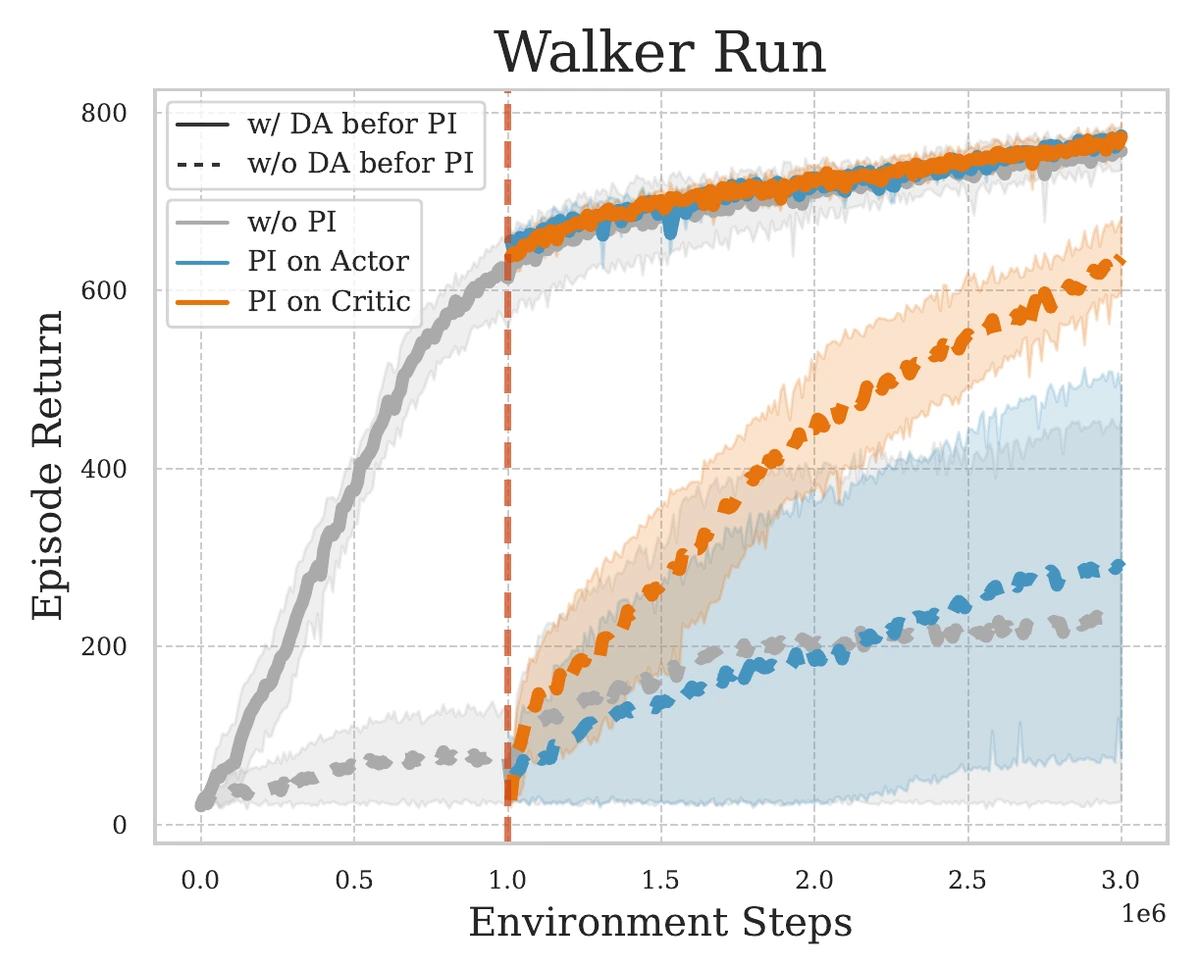
Understanding when and where visual RL loses its ability to keep learning.
Haoyu Wang, Guozheng Ma, Ziqiao Meng, Zeyu Qin, Li Shen, Zhong Zhang, Bingzhe Wu, Liu Liu, Yatao Bian, Tingyang Xu, Xueqian Wang, Peilin Zhao
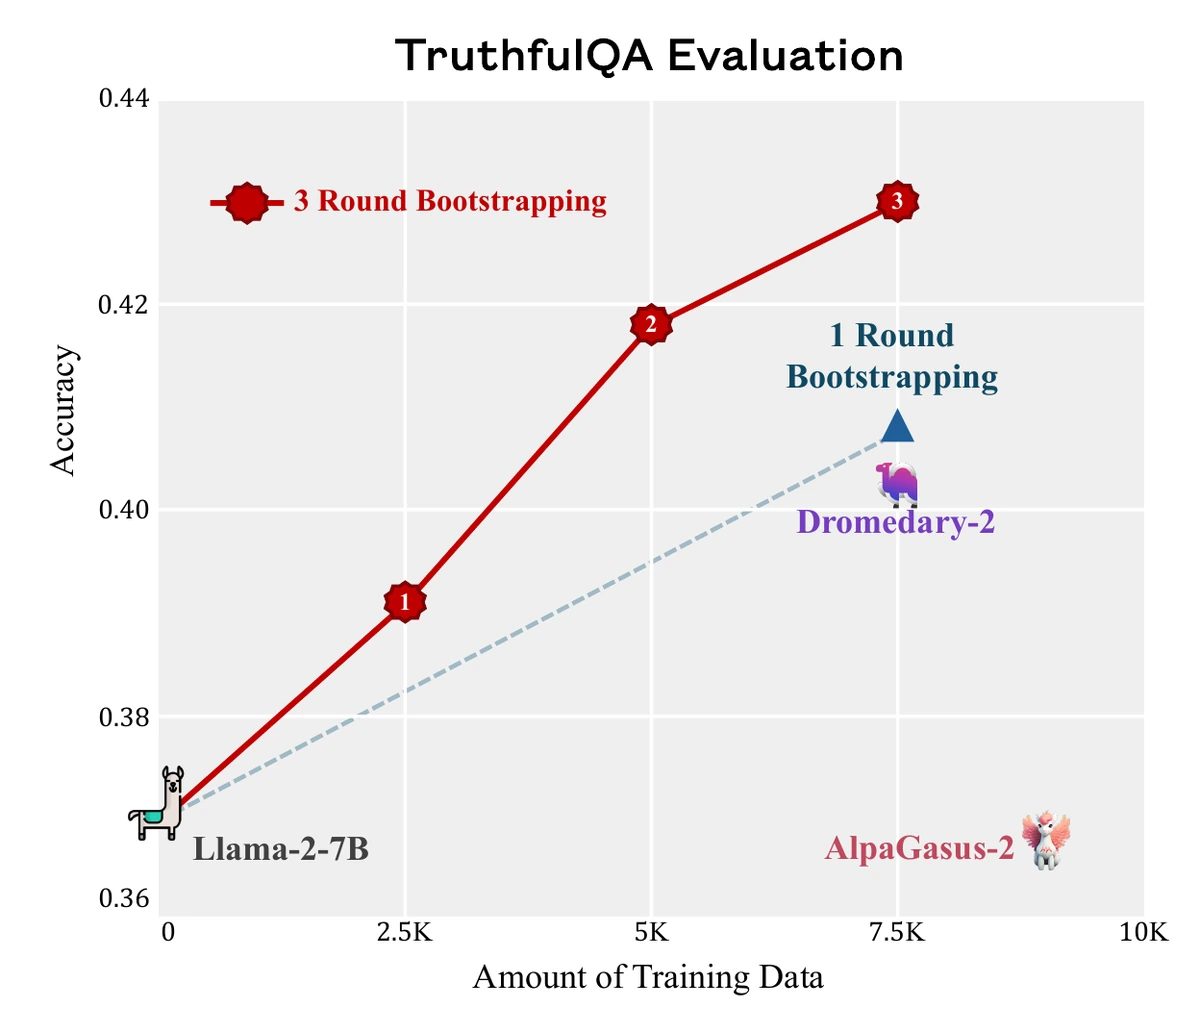
Iterative bootstrapping uses a language model’s improving few-shot capabilities and diverse generated examples to strengthen its self-alignment.
Lu Li*, Jiafei Lyu*, Guozheng Ma, Zilin Wang, Zhenjie Yang, Xiu Li, Zhiheng Li * Equal contribution
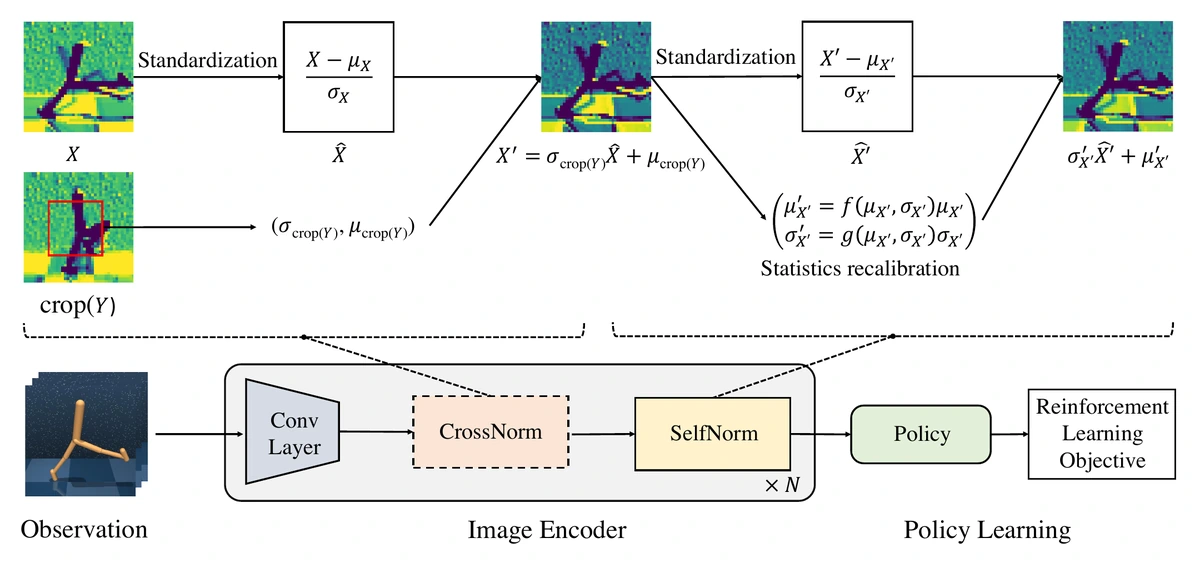
Combining CrossNorm and SelfNorm improves the ability of visual RL policies to generalize under changed visual observations.
Guozheng Ma, Linrui Zhang, Haoyu Wang, Lu Li, Zilin Wang, Zhen Wang, Li Shen, Xueqian Wang, Dacheng Tao
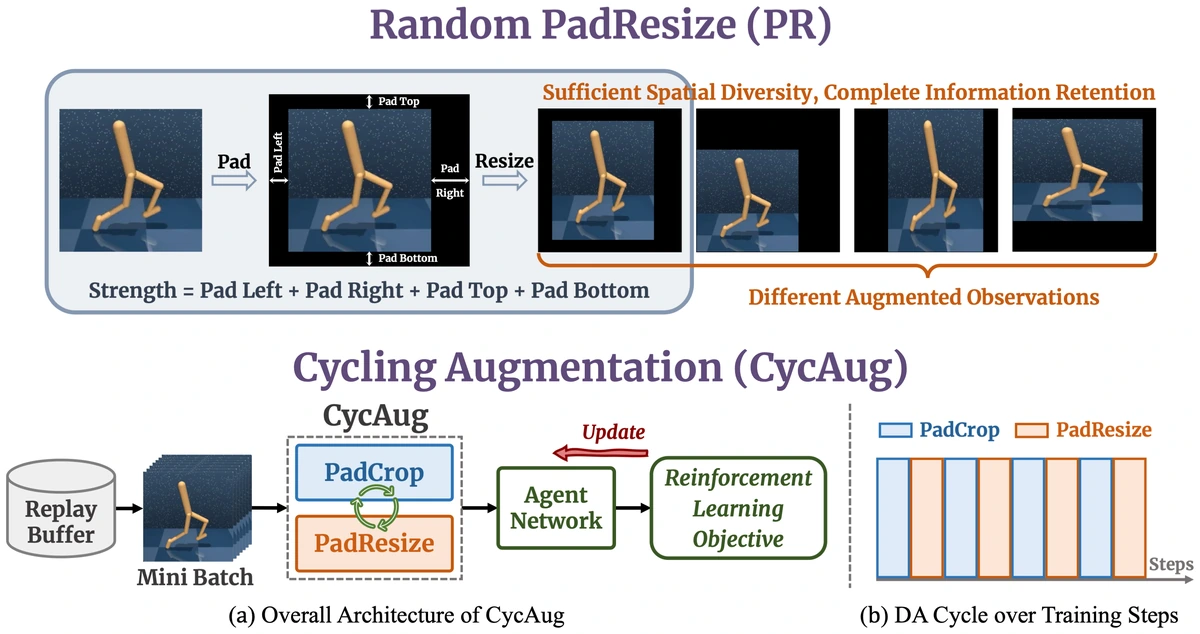
Balancing visual diversity and training stability with Rand PR and CycAug.
Zhecheng Yuan, Guozheng Ma, Yao Mu, Bo Xia, Bo Yuan, Xueqian Wang, Ping Luo, Huazhe Xu
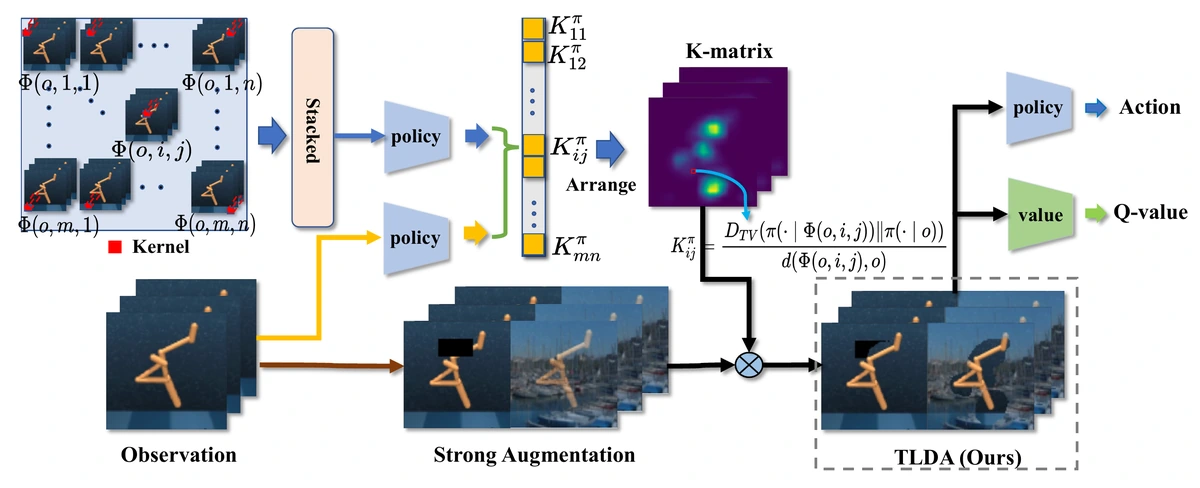
Task-aware augmentation protects important pixels while diversifying observations to improve both sample efficiency and visual RL generalization.
No matching publications Try a different area, theme, role, or status.
Clear filters